Speechmatics
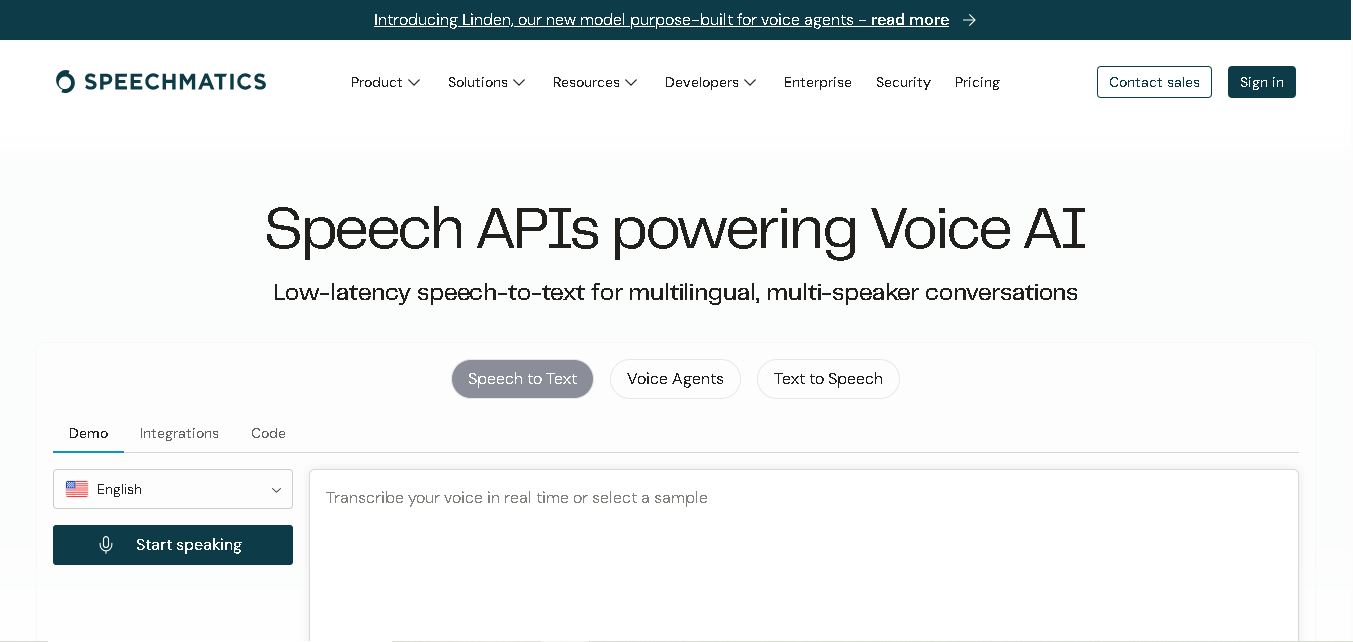
Speechmatics provides multilingual speech-to-text APIs for live and recorded audio. It supports 55+ languages, speaker diarization, custom dictionaries, translation, and low-latency transcription. Developers can integrate its capabilities into voice agents, contact centers, media workflows, healthcare applications, and other products that need accurate, scalable speech recognition across diverse accents, dialects, and conversations.
What is Speechmatics?
Speechmatics is a speech AI service that converts live or recorded audio into text for applications, workflows, and voice experiences. It provides speech-to-text APIs with multilingual transcription, speaker diarization, translation, summarization, and customization features. Developers can process conversations in real time or batch mode, while organizations can choose cloud, on-premise, or on-device deployment depending on performance, privacy, and infrastructure requirements.
Speechmatics, founded in 2006 in Cambridge, supports 55+ transcription languages and 69 translation pairs. Its real-time service can deliver final transcripts in under one second, with initial results arriving within milliseconds. New accounts receive $100 in free credit with no credit card required. The platform supports cloud, on-premise, and on-device deployment options, plus speaker diarization, custom dictionaries, word timings, translation, and summarization. Speechmatics reports SOC 2 Type II, ISO 27001:2022, GDPR, and HIPAA compliance for suitable enterprise and regulated workflows.
- Founder / Leadership: Dr. Tony Robinson (Founder) and Katy Wigdahl (CEO)
- Launch Year: 2006
Use Cases:
- Transcribing live stream broadcasts, podcasts, and video archives with sub-second latency and precise word-level timestamps
- Powering conversational voice agents and AI assistants with built-in turn detection and real-time audio streaming
- Analyzing call center customer conversations for sentiment, topic extraction, entity detection, and PII redaction
- Deploying speech recognition models on-premises or air-gapped in secure enterprise environments using Kubernetes containers
Technology:
- Multilingual neural ASR engine supporting code-switching and dynamic mid-sentence language detection
- Real-time WebSocket and batch REST API architectures optimized for cloud, edge, and on-premises deployments
- Built-in generative AI add-ons for automatic audio summarization, translation, and custom vocabulary dictionary mapping
Target Users:
- Voice AI developers and software engineers embedding speech-to-text into customer support platforms and AI agents
- Media, broadcasting, and podcasting platforms seeking high-accuracy automated subtitling and closed captioning
- Healthcare and medical transcription providers utilizing domain-specific language models (e.g., Oak 1 Medical)
- Content creators using writing tools to draft voice-over scripts, interview transcripts, and media summaries
Corporate Entity: Operates as Speechmatics Ltd. (Cambridge, UK, London, & USA)
Key features of Speechmatics
Speechmatics' key features are
- Multilingual Speech Recognition (50+ Languages): Handles complex accents, background noise, and mid-sentence code-switching without needing upfront language selection.
- Real-Time & Pre-Recorded Audio Processing: Delivers sub-second low-latency streaming transcription alongside high-throughput batch file processing.
- Speaker Diarization & Formatting: Identifies distinct speakers automatically and applies smart formatting, capitalization, advanced punctuation, and timing metadata.
- Domain-Specific AI Models: Specialized transcription models tailored for general audio (Melia 1), medical dictation (Oak 1), and conversational voice agents (Linden 1).
- Built-In Audio Intelligence: Optional add-on features including automatic language translation, chapter generation, sentiment analysis, topic detection, and PII redaction.
- Custom Dictionary & Vocabulary Customization: Enables custom term prompting to accurately capture specialized jargon, brand names, and industry terminology.
- Flexible Enterprise Deployment: Available as a cloud-hosted SaaS API or as self-hosted Docker/Kubernetes containers for strict regulatory compliance.
Speechmatics Pricing
Speechmatics operates on a flexible pay-as-you-go credit model alongside custom enterprise volume contracts.
Free / Pay-As-You-Go Tier:
- Starts with $100 in free API credits (no credit card required)
- Pre-recorded General Purpose (Melia 1): $0.12 / audio hour
- Pre-recorded Enhanced Model: $0.38 / audio hour
- Medical Model (Oak 1): $0.15 / audio hour
- Text-to-Speech Synthesis: $0.011 per 1,000 characters (First 1 million characters free)
Enterprise Tier:
- Custom quote-based enterprise contract
- Includes a dedicated CSM & Solutions Engineer, unlimited concurrent sessions, self-hosted container options, custom Master Services Agreement (MSA), and SSO add-ons.
Disclaimer: Volume discounts of up to 25% apply automatically as credit consumption scales. For enterprise quote requests and container trials, visit speechmatics.com/pricing.
Who is using Speechmatics?
Speechmatics is designed for technology scaleups, media enterprises, and healthcare providers, including
- Voice AI Developers: Building real-time conversational agents and customer service chatbots
- Contact Centers & BPOs: Analyzing customer support calls for compliance, sentiment, and agent coaching
- Media & Broadcasting Networks: Generating automated captions, sub-titles, and searchable transcripts
- Healthcare Systems: Converting clinical dictations and patient notes into structured EHR data
- Content Creators: Using writing tools to convert meeting transcripts into blog posts, social summaries, and newsletter updates
Best Speechmatics Alternatives
Some of the strongest Speechmatics alternatives include
- Deepgram
- AssemblyAI
- OpenAI Whisper
- Rev AI
- Google Cloud Speech-to-Text
- Amazon Transcribe
Pros and Cons of Speechmatics
Pros
- Industry benchmark for accent handling, code-switching, and audio recognition in noisy environments
- Offers self-hosted container options for full data sovereignty and air-gapped deployments
- Generous starting tier offering $100 in free credits for developer testing
- The built-in audio intelligence layer handles translation, sentiment analysis, and PII redaction without needing separate APIs
Cons
- Advanced add-ons like translation and summarization incur extra per-hour charges
- Self-hosted on-premises deployment requires enterprise-level contractual commitments
- Custom vocabulary tuning requires fine-tuning dictionary payloads for best performance
Why Choose Speechmatics?
Speechmatics is a premier choice for organizations that require highly accurate, accent-agnostic speech-to-text processing. Unlike generic cloud provider APIs, Speechmatics focuses on low-latency accuracy, seamless code-switching, and flexible deployment models across cloud and self-hosted infrastructure.
- Unrivaled accuracy across 50+ languages, multiple dialects, and overlapping speech
- Flexible cloud SaaS and on-premises container deployment choices
- Generous $100 free credit tier for rapid API integration and prototyping
- Integrated Voice AI capabilities, including translation, sentiment, and PII redaction
Speechmatics vs. Competitors
The main difference between Speechmatics, Deepgram, AssemblyAI, and OpenAI Whisper is that Speechmatics offers hybrid deployment options (cloud and containerized on-prem) with industry-leading accent recognition and code-switching capabilities, whereas OpenAI Whisper is an open-source model requiring self-hosting infrastructure, Deepgram focuses heavily on ultra-low latency real-time API performance, and AssemblyAI specializes in LLM-powered audio intelligence tools. Speechmatics stands out for enterprise deployment flexibility and global language accuracy.
| Feature / Tool | Speechmatics (speechmatics.com) | Deepgram | AssemblyAI | OpenAI Whisper |
|---|---|---|---|---|
| Core Focus | Enterprise Multilingual ASR & Voice AI | Low-Latency Real-Time Voice APIs | AI-Powered Speech & Audio Intelligence | Open-Source Speech Recognition Model |
| Deployment Options | Cloud SaaS & On-Prem Containers | Cloud & On-Premises | Cloud API Only | Self-Hosted / Open-Source & Cloud API |
| Code-Switching Support | Yes (seamless mid-sentence switching) | Limited per model | Single-language detection per stream | Limited per chunk |
| Audio Intelligence Add-Ons | Yes (PII, Sentiment, Summaries) | Yes (Summarization, Sentiment) | Yes (LeMieux LLM features) | Requires a third-party LLM pipeline |
| Starting Price Range | $100 free credits / $0.12–$0.38/hr | $200 free credits / ~$0.25/hr | Free tier / ~$0.37/hr | Free open-source or $0.006/min ($0.36/hr) |
| Best For | Enterprise & global multilingual voice systems | High-speed real-time voice agents | Developer-friendly LLM audio workflows | Open-source self-hosted speech projects |
How do we rate Speechmatics?
| Parameter | Rating (out of 5) |
|---|---|
| Transcription Accuracy & Accent Handling | 4.9 |
| Latency & Real-Time Streaming Performance | 4.8 |
| Deployment Flexibility (Cloud vs Containers) | 4.9 |
| Audio Intelligence & Add-on Features | 4.7 |
| Value for Money | 4.7 |
| Overall Score | 4.80 |
Speechmatics Review
Speechmatics has established itself as an essential provider in the voice recognition and speech-to-text market. In an era where conversational AI and automated transcription are integral to enterprise operations, Speechmatics delivers reliable accuracy across diverse global accents and noisy real-world environments. Its developer-first approach—highlighted by $100 in free credits, straightforward REST/WebSocket APIs, and full Docker container support—makes it an ideal choice for teams scaling voice capabilities across multi-cloud and on-premise infrastructure.
Conclusion
Speechmatics is a strong choice when your workflow depends on accurate, multilingual speech recognition rather than simple transcription alone. Its combination of real-time and batch processing, speaker diarization, customization, broad language coverage, and flexible deployment makes it suitable for developers and enterprises. With free starting credit and enterprise options, Speechmatics can support experimentation as well as larger production workloads.
FAQ
What can I use Speechmatics for?
Speechmatics is useful when you need dependable transcription for meetings, calls, media, voice agents, or other audio workflows. It handles both live and prerecorded speech, supports many languages, and includes speaker diarization. For production projects, you can also choose cloud, on-premise, or on-device deployment based on your requirements today easily.
How many languages does Speechmatics support?
Speechmatics currently supports 55+ transcription languages, including English, Hindi, Bengali, Marathi, Tamil, Urdu, Arabic, Spanish, French, German, Japanese, Korean, and Vietnamese. Its language coverage is designed around accents and dialects rather than narrow regional variants. This makes it practical for multilingual products serving international users and diverse speakers and teams.
Does Speechmatics provide real-time transcription?
Yes. Speechmatics offers real-time speech-to-text with initial transcript results arriving within milliseconds and final transcripts delivered in under one second, depending on configuration. This makes it suitable for live captions, voice agents, conversational applications, contact centers, and interactive experiences where waiting for a complete recording would reduce responsiveness or usability.
Can Speechmatics identify different speakers?
Speechmatics provides speaker and channel diarization, allowing transcripts to show who said what during conversations. The real-time service identifies up to 50 speakers by default, with support for increasing that number to 100. This is particularly helpful for meetings, interviews, calls, legal recordings, healthcare conversations, and other multi-speaker audio workflows.
How much does Speechmatics cost?
Speechmatics offers usage-based pricing for transcription, with costs varying by model and processing mode. Its current calculator lists models such as Melia 1, Standard, Enhanced, and Oak 1 at different hourly rates. New accounts receive $100 in free credit without requiring a credit card, making initial testing straightforward for developers.
What features does Speechmatics offer besides transcription?
Speechmatics provides more than transcription. Depending on the model and workflow, features include speaker diarization, word-level timestamps, punctuation, custom dictionaries, confidence scores, translation, summaries, and chapters. Its APIs can support voice agents, contact centers, healthcare, media, accessibility, search, analytics, and other applications built around spoken language and audio data today.
User Reviews
No reviews yet for Speechmatics.
Featured Tools
Featured AI tools from TechShark
Melody Genie
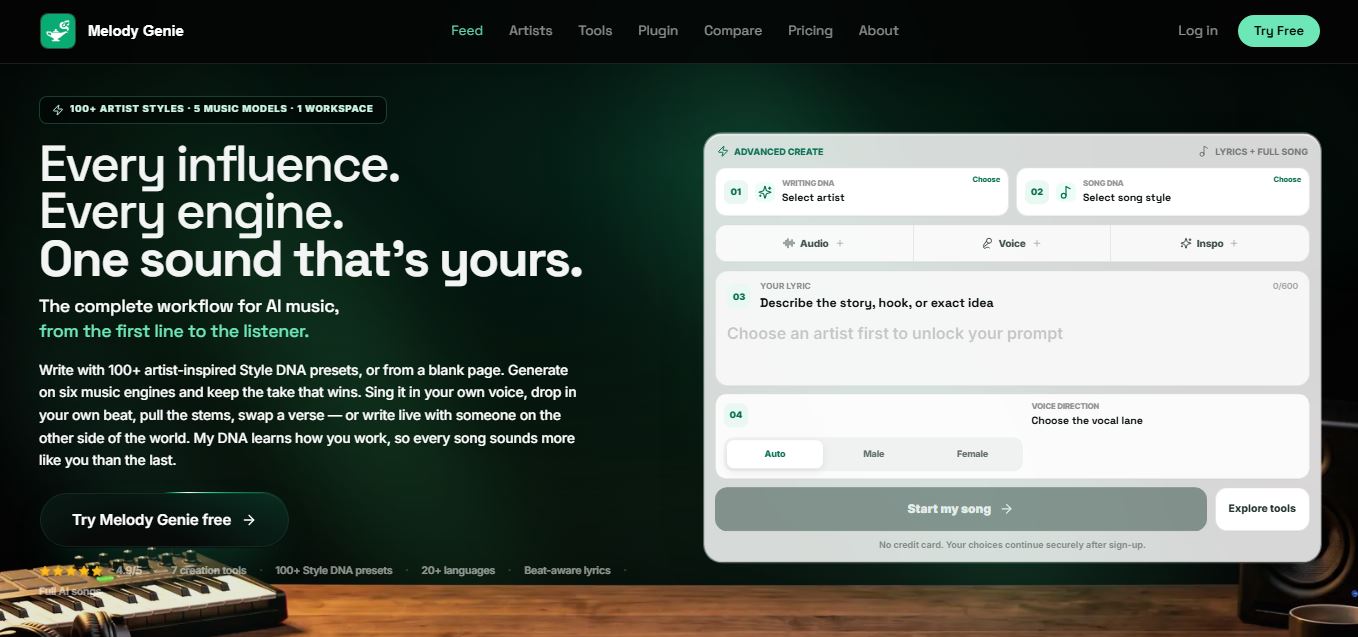
MelodyGenie is an AI-powered music generator that creates original songs from simple text prompts. Users can choose styles, moods, and genres, then instantly generate melodies and full tracks, making it easy for creators, marketers, and hobbyists to produce custom music without musical expertise.
Freemium
Kimi AI
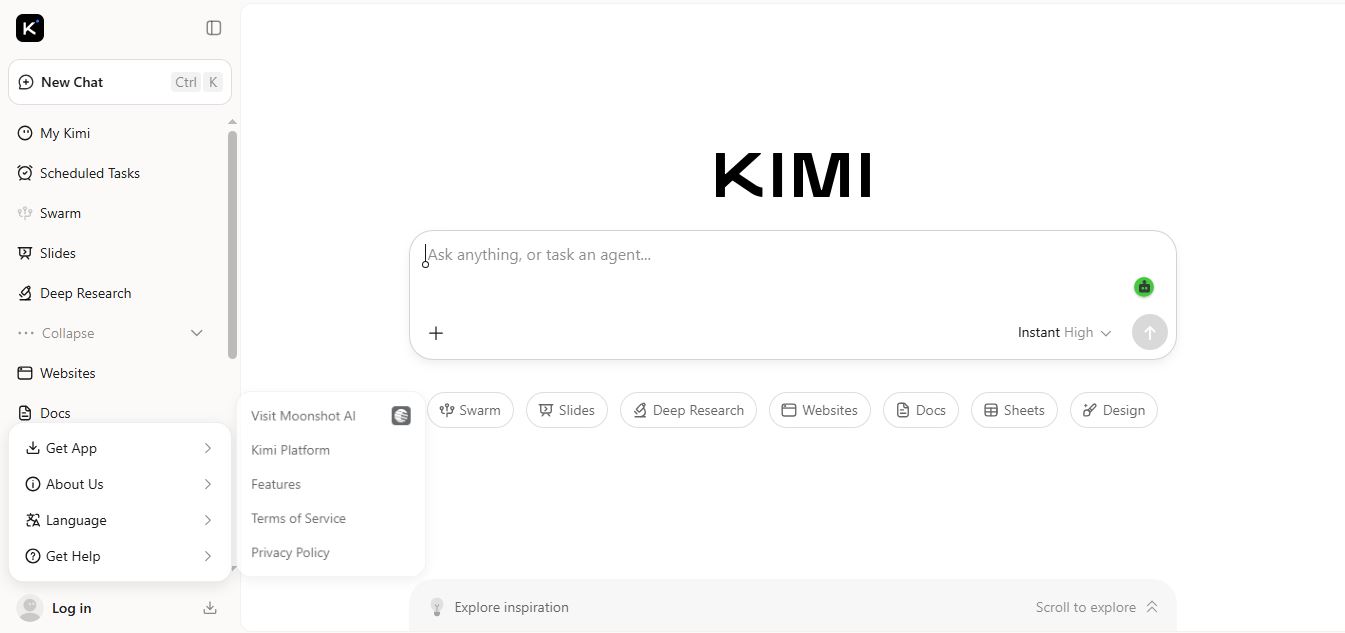
Kimi AI is an advanced AI assistant developed by Moonshot AI that helps you chat, research, write, code, and automate tasks in one place. It supports web search, file analysis, and multimodal inputs, and can even run autonomous “agent” workflows to complete complex tasks end-to-end.
Freemium
Fashion Diffusion AI
Fashion Diffusion is an AI-powered fashion design platform that helps brands and designers create clothing designs, virtual try-ons, AI models, product photos, and marketing visuals faster and cost-effectively.
Paid
Veo 4
Veo 4 AI is an AI video creation platform that generates dramatic videos from text, images, audio, and video prompts using realistic motion and synchronized sound.
Paid
Alternatives
Alternatives to Speechmatics
The best Speechmatics alternatives include Deepgram, AssemblyAI, OpenAI Whisper, Rev AI, Google Cloud Speech-to-Text, and Amazon Transcribe. These platforms provide automatic speech recognition (ASR) and audio intelligence APIs. While Speechmatics excels in accent handling, code-switching, and flexible on-premise container deployment, alternatives like Deepgram prioritize ultra-low real-time latency, AssemblyAI offers LLM-native workflow integrations, and OpenAI Whisper provides popular open-source models.
 4.6
Text to Speech Online
Text-to-Speech
Text-to-Speech Online converts written content into natural-sounding speech using Microsoft Azure Edge TTS technology. It offers multilingual voices, adjustable speed and pitch, voice previews, pause controls, and MP3 or WAV downloads. The service can support video narration, podcasts, audiobooks, educational materials, voice assistants, and multilingual content creation.
 4.9
ElevenLabs
Voice Generator
ElevenLabs is an AI-powered voice generation platform that helps users create realistic speech, clone voices, and build conversational voice agents. It converts text into expressive audio, supports multiple languages, and offers APIs for developers, enabling voiceovers, dubbing, customer support automation, and interactive audio experiences.
 4.9
Speaktor
Text-to-Speech
Speaktor is an AI-powered text-to-speech platform that converts written content into natural-sounding voiceovers in 50+ languages. It lets users upload text, documents, or URLs and generate downloadable audio, making it ideal for content creation, accessibility, learning, and multilingual voice generation workflows.
 4.7
Murf AI
Text-to-Speech
Murf.ai is an AI-powered text-to-speech studio and voice generator platform that enables users to create professional voiceovers, perform voice cloning, edit audio from scripts, and synchronize AI speech with visual content.
 4.8
Speechki
Text-to-Speech
Speechki turns written content into realistic spoken audio using more than 1,100 voices across 80 languages. It offers customization for speed, tone, pitch, pauses, prosody, and pronunciation, making it useful for creators, educators, businesses, podcasters, and anyone who wants to consume or distribute content through audio.
 4.8
Rev
Text-to-Speech
Rev is a speech-to-text platform providing AI-powered and 99% accurate human transcription, closed captioning, burned-in video subtitles, and developer speech APIs across 37+ languages for legal, media, and enterprise organizations.
 4.7
TTSLabs
Gaming
TTSLabs is an AI-powered text-to-speech platform built specifically for live streamers and content creators. It integrates directly with streaming dashboards like Streamlabs and StreamElements to give Twitch and YouTube streamers advanced customization over donation alerts, custom AI voices (including streamer and pop-culture character profiles), sound clips, and profanity filtering.
 4.8
Saga
Text-to-Speech
Saga is a high-quality premade synthetic voice profile available within the ElevenLabs AI voice platform. Optimized for expressive narrative storytelling, audiobooks, character dialogue, and conversational applications, Saga delivers natural intonation across dozens of languages.
 4.8
TTSReader
Text-to-Speech
TTSReader is a browser-based text-to-speech reader for listening to articles, documents, books, and webpages. It offers languages, voices, speed controls, text highlighting, and audio export. Its free tier supports unlimited use of non-premium voices, while premium plans add AI voices, exporting, sharing, and commercial capabilities. It suits students, writers, accessibility.