Text-to-Speech AI tools
Explore the best Text-to-Speech AI tools, filtered from the TechShark directory.
 4.9
KittenTTS Web
Text-to-Speech
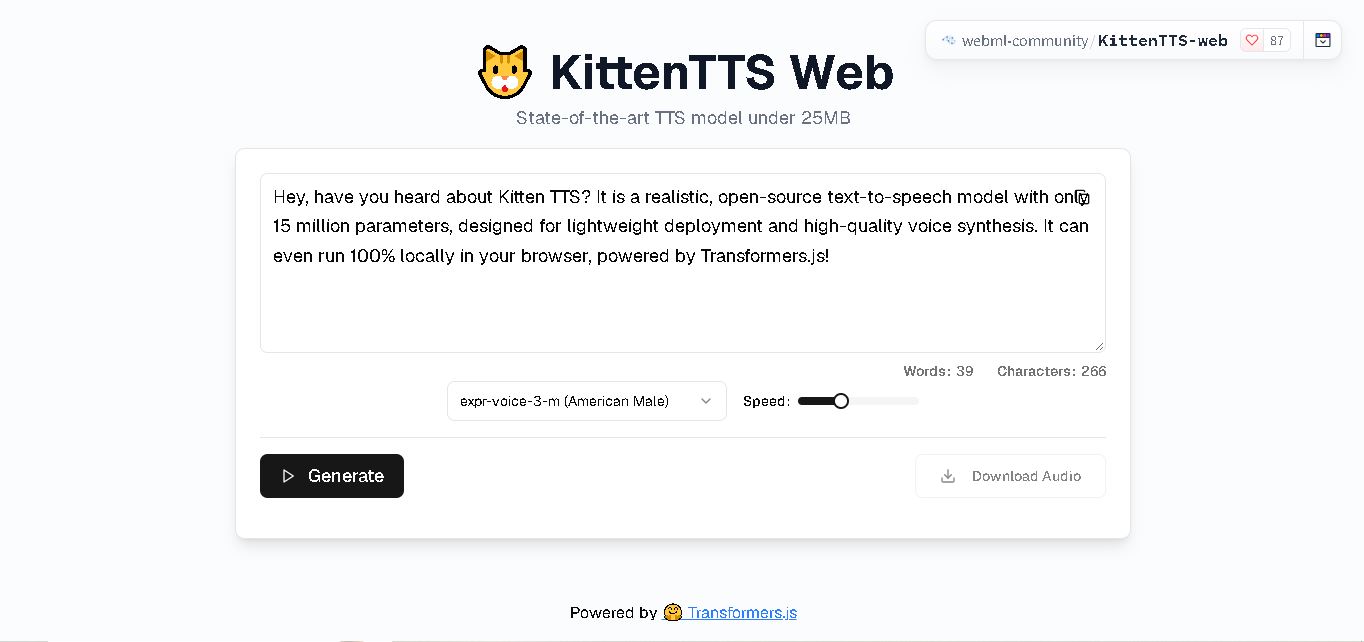
KittenTTS Web is a lightweight text-to-speech demo hosted on Hugging Face Spaces. It helps users explore how written text can be transformed into spoken audio using neural voice synthesis. The project is particularly relevant to developers, content creators, and accessibility-focused users interested in experimenting with compact speech generation technology directly through a web browser.
FreeView tool
 4.9
Parler-TTS
Text-to-Speech
Parler-TTS is an open-source text-to-speech tool that transforms written content into natural-sounding audio. It lets developers describe voice characteristics using natural language, including pitch, speaking speed, and recording quality. With publicly available model weights, training resources, and customizable checkpoints, it supports experimentation, research, and tailored speech-generation applications across projects.
FreeView tool
 4.9
IMS Toucan
Text-to-Speech
IMS Toucan is an open-source text-to-speech toolkit from the University of Stuttgart designed for multilingual speech generation. It converts text into audio and provides tools for inference, voice and prosody control, and model training. Supporting more than 7,000 languages, it serves developers and researchers exploring technology across linguistic contexts.
FreeView tool
 4.8
Verbatik
Text-to-Speech
Verbatik AI helps users create realistic voiceovers, clone voices, generate music, and produce multimedia content using artificial intelligence. With multilingual speech, customizable voice settings, and developer APIs, it supports content creators, marketers, educators, and businesses. The platform simplifies audio production, video creation, and content localization from one workspace.
FreemiumView tool
 4.8
Narration Box
Text-to-Speech
Narration Box is an AI voice generator for creating realistic voiceovers, audiobooks, podcasts, and educational audio from text. It offers over 1,500 AI narrators, 80+ languages and accents, voice cloning, and customizable emotional delivery. Its editing tools help creators produce consistent, multilingual audio content for personal and professional projects.
FreemiumView tool
 4.7
AudioBot
Text-to-Speech
AudioBot converts written text into natural-sounding speech using AI-generated voices. It supports multiple languages and regional accents, making it useful for video voiceovers, presentations, educational materials, and audio content. Users can generate and download audio files, helping simplify narration workflows without requiring traditional recording equipment or voice talent.
FreemiumView tool
 4.7
Audie AI
Text-to-Speech
Audie AI is an audiobook creation tool that converts written manuscripts into narrated audio using AI-generated voices. It helps authors and publishers simplify production, explore different narration styles, and reduce reliance on traditional recording studios. With voice selection, advertised voice cloning, and downloadable audio, it supports more accessible audiobook creation for independent creators.
FreemiumView tool
 4.6
Speechelo
Text-to-Speech
Speechelo is a text-to-speech tool designed to help creators turn written scripts into voiceovers. It offers different voices, languages, tones, and audio adjustments for creating narration. Video creators, educators, marketers, and content teams can use it to produce audio for tutorials, presentations, promotional videos, and other digital content projects.
PaidView tool
 4.7
Leelo AI
Text-to-Speech
Leelo AI helps you turn written content into natural-sounding speech without recording your own voice. You can choose from 800+ voices across 142 languages and accents, adjust available voice settings, generate audio, store files in the cloud, export recordings, and use generated speech commercially for different content and communication needs.
FreemiumView tool
 4.7
MyVocal AI
Text-to-Speech
MyVocal AI helps creators turn written content and voice recordings into natural-sounding audio. Users can clone voices, generate multilingual speech, create AI song covers, transcribe recordings, and produce music from text. Its combination of voice customization, emotion control, and multilingual generation makes it useful for content, narration, music, products, and interactive experiences.
FreemiumView tool
 4.8
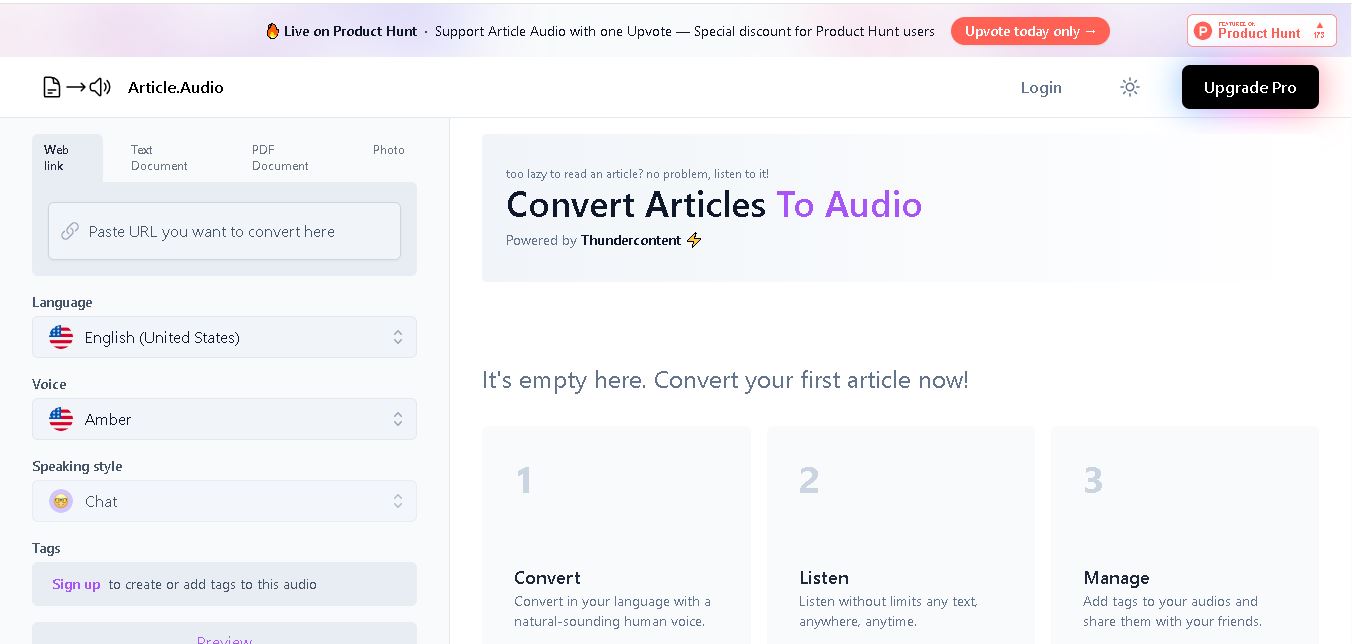
Article Audio
Text-to-Speech
Article.Audio turns online articles into listenable audio from a simple web link. You can choose a language, voice, and speaking style to create a more personalized listening experience. It is useful for readers who want to consume articles while commuting, exercising, working, or handling other activities.
FreemiumView tool
 4.8
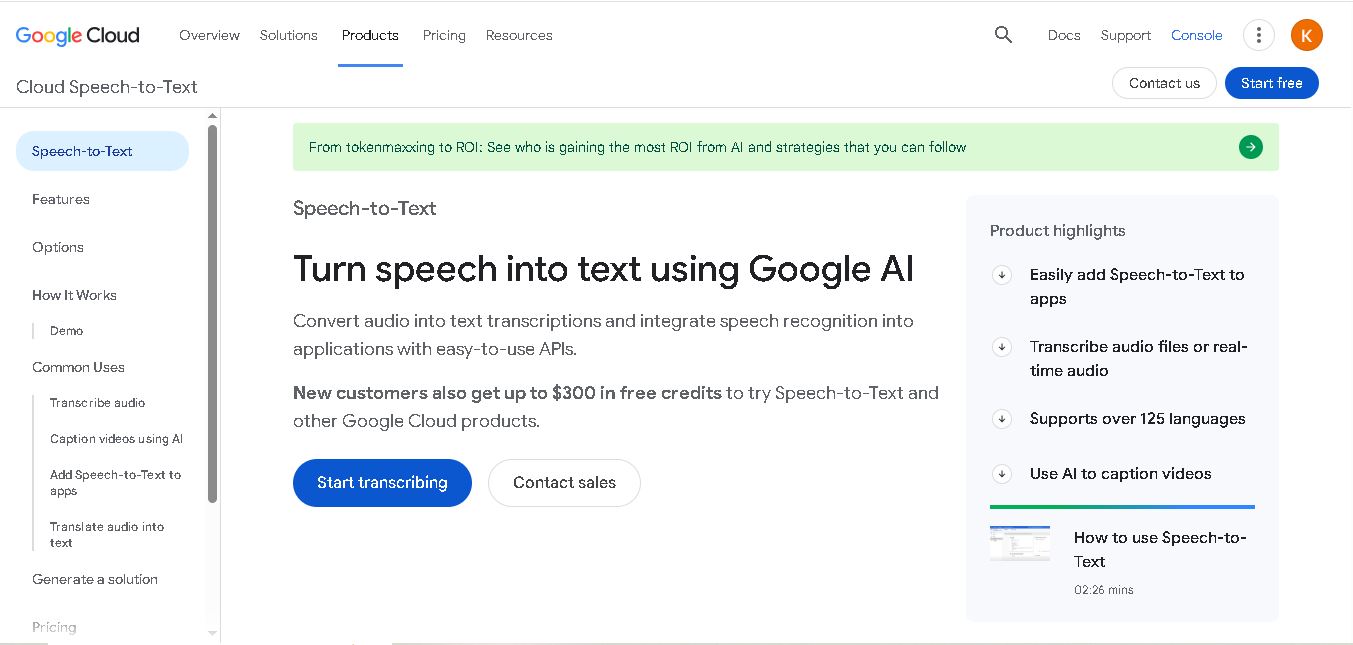
Google Cloud Speech-to-Text
Text-to-Speech
Google Cloud Speech-to-Text helps developers turn spoken audio into text for applications, captions, voice commands, meetings, calls, and searchable content. With streaming recognition, multilingual support, model adaptation, speaker diarization, and multiple transcription methods, it provides speech recognition capabilities for applications and enterprise workflows. It fits teams seeking integrated transcription workflows.
FreemiumView tool