
AssemblyAI
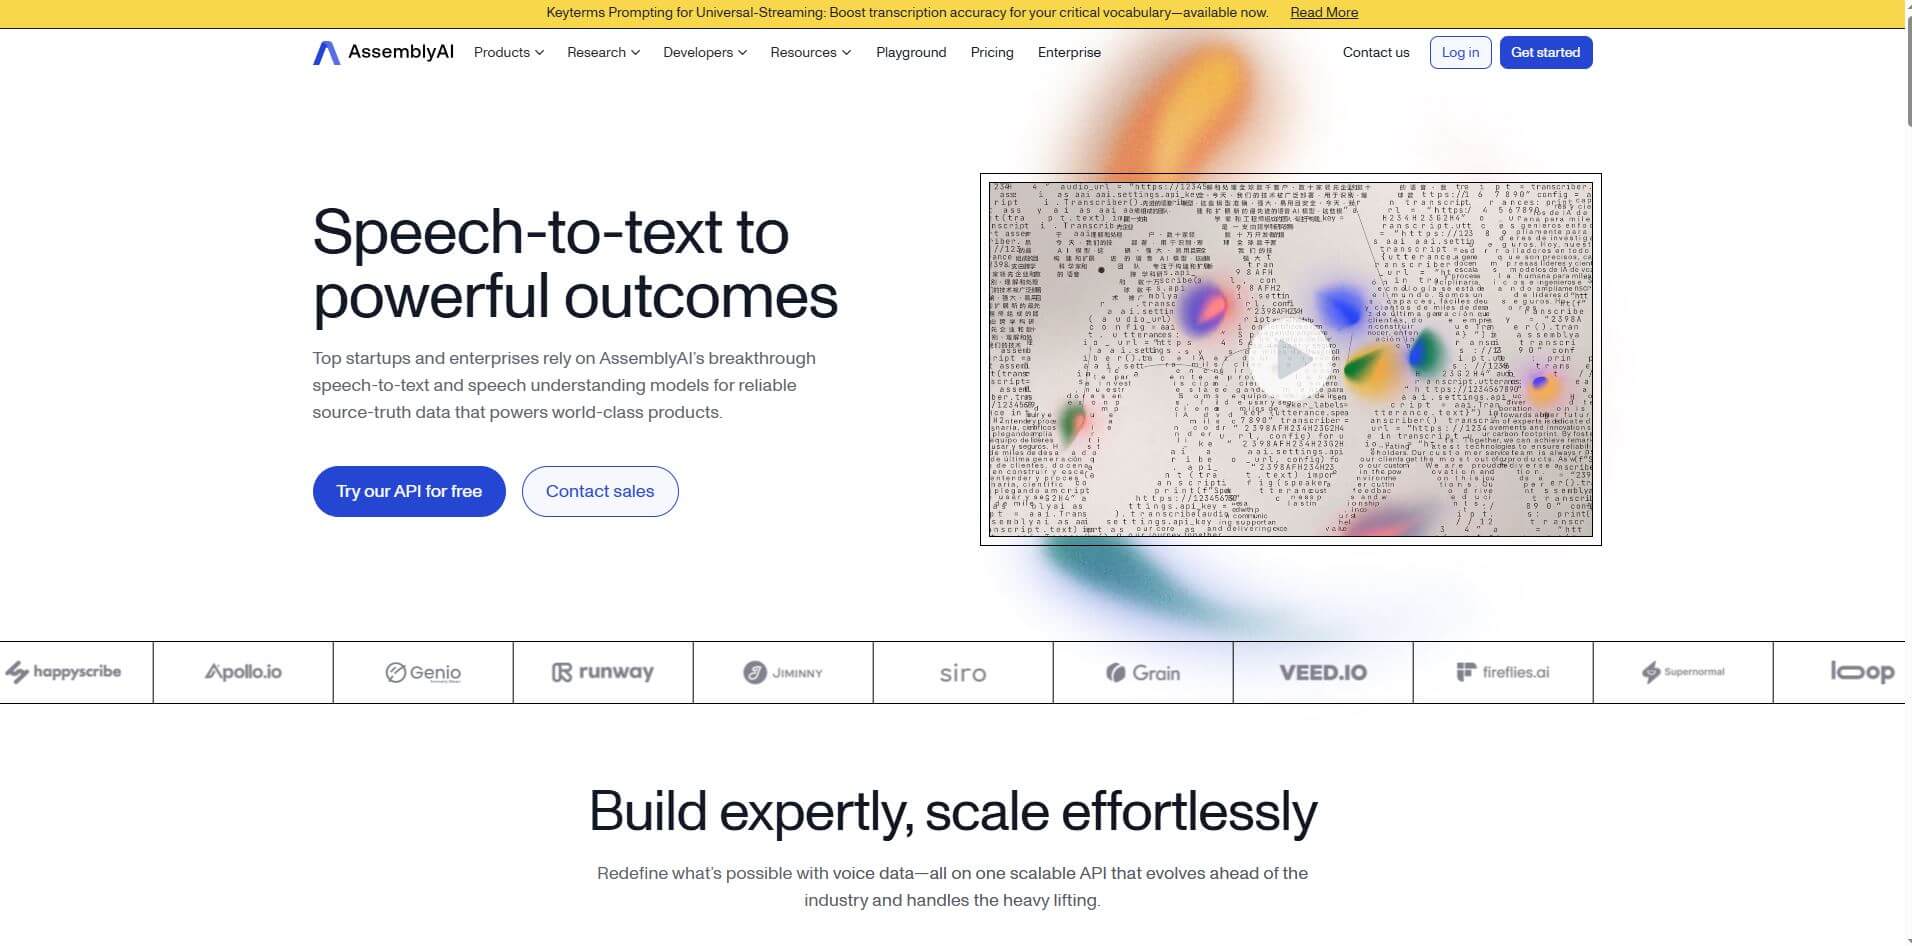
AssemblyAI is an AI-powered speech-to-text and audio intelligence platform that converts audio and video into actionable insights with accuracy, speed, and enterprise-grade security.
What is AssemblyAI?
- Founder: Johan Boye
- Launch: 2017
- Use Cases: Podcast transcription, video captioning, call analysis, content indexing, AI-driven audio insights, accessibility improvements
- Technology: Deep learning, speech recognition, natural language processing (NLP), machine learning models
AssemblyAI is an AI-powered text-to-speech platform that processes and extracts meaningful data out of audio and video content through deep learning and state-of-the-art speech-to-text technology. AssemblyAI uses advanced deep learning and natural language processing (NLP) models to quickly and accurately turn speech into text, offer real-time speech recognition, and create insights from audio. Businesses, developers, and creators turn to AssemblyAI to eliminate the hassle of manual transcription for their podcasts, webinars, meetings, and customer support calls. In addition to transcription, AssemblyAI develops more advanced capabilities to provide users with more profound insights from their spoken content, such as sentiment analysis, topic detection, content moderation capabilities, and named entity recognition capabilities. AssemblyAI integrates seamlessly into your existing applications, workflows, and platforms through its API first design, so businesses and developers can initiate scalable audio intelligence solutions in a short amount of time.
AssemblyAI takes data security seriously and provides enterprise-grade security and privacy measures to ensure that sensitive audio remains secure and compliant. By changing audio into actionable data, AssemblyAI helps companies be more productive, allows better accessibility, and extracts value from their audio and video content.
AssemblyAI Video/Demo
People are also reading
FAQ
What platforms support AssemblyAI?
AssemblyAI is accessible via a simple API, allowing integration with web applications, mobile apps, and server-side workflows.
Can AssemblyAI handle multiple languages?
Yes, AssemblyAI supports a variety of languages and accents, providing accurate transcription across diverse audio sources.
Is AssemblyAI suitable for real-time transcription?
Yes, it offers streaming capabilities for live audio, making it ideal for webinars, calls, and live broadcasts.
How secure is my data with AssemblyAI?
AssemblyAI implements enterprise-grade security and compliance standards to ensure sensitive audio and video content is fully protected.
Can AssemblyAI detect topics or sentiments in audio?
Yes, it includes advanced features like sentiment analysis, entity recognition, and topic detection to extract deeper insights from audio content.
User Reviews
No reviews yet for AssemblyAI.
Featured Tools
Featured AI tools from TechShark
Melody Genie
MelodyGenie is an AI-powered music generator that creates original songs from simple text prompts. Users can choose styles, moods, and genres, then instantly generate melodies and full tracks, making it easy for creators, marketers, and hobbyists to produce custom music without musical expertise.
Freemium
Kimi AI
Kimi AI is an advanced AI assistant developed by Moonshot AI that helps you chat, research, write, code, and automate tasks in one place. It supports web search, file analysis, and multimodal inputs, and can even run autonomous “agent” workflows to complete complex tasks end-to-end.
Freemium
Fashion Diffusion AI
Fashion Diffusion is an AI-powered fashion design platform that helps brands and designers create clothing designs, virtual try-ons, AI models, product photos, and marketing visuals faster and cost-effectively.
Paid
Veo 4
Veo 4 AI is an AI video creation platform that generates dramatic videos from text, images, audio, and video prompts using realistic motion and synchronized sound.
Paid
Alternatives
Alternatives to AssemblyAI
AssemblyAI is an AI-powered speech-to-text platform that offers advanced transcription, real-time speech recognition, and AI-driven audio analysis tools, enabling businesses to extract valuable insights, automate workflows, and improve accessibility across podcasts, calls, videos, and other audio content.
 4.9
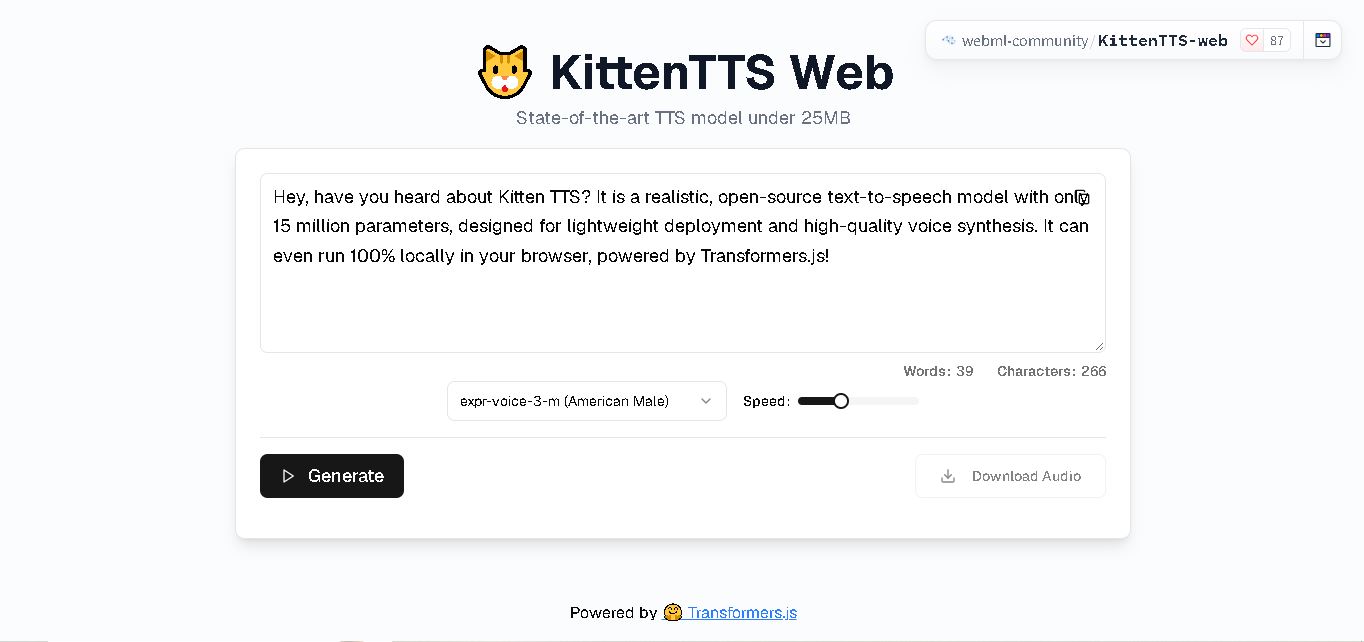
KittenTTS Web
Text-to-Speech
KittenTTS Web is a lightweight text-to-speech demo hosted on Hugging Face Spaces. It helps users explore how written text can be transformed into spoken audio using neural voice synthesis. The project is particularly relevant to developers, content creators, and accessibility-focused users interested in experimenting with compact speech generation technology directly through a web browser.
 4.9
Parler-TTS
Text-to-Speech
Parler-TTS is an open-source text-to-speech tool that transforms written content into natural-sounding audio. It lets developers describe voice characteristics using natural language, including pitch, speaking speed, and recording quality. With publicly available model weights, training resources, and customizable checkpoints, it supports experimentation, research, and tailored speech-generation applications across projects.
 4.9
IMS Toucan
Text-to-Speech
IMS Toucan is an open-source text-to-speech toolkit from the University of Stuttgart designed for multilingual speech generation. It converts text into audio and provides tools for inference, voice and prosody control, and model training. Supporting more than 7,000 languages, it serves developers and researchers exploring technology across linguistic contexts.
 4.8
Verbatik
Text-to-Speech
Verbatik AI helps users create realistic voiceovers, clone voices, generate music, and produce multimedia content using artificial intelligence. With multilingual speech, customizable voice settings, and developer APIs, it supports content creators, marketers, educators, and businesses. The platform simplifies audio production, video creation, and content localization from one workspace.
 4.8
Narration Box
Text-to-Speech
Narration Box is an AI voice generator for creating realistic voiceovers, audiobooks, podcasts, and educational audio from text. It offers over 1,500 AI narrators, 80+ languages and accents, voice cloning, and customizable emotional delivery. Its editing tools help creators produce consistent, multilingual audio content for personal and professional projects.
 4.7
AudioBot
Text-to-Speech
AudioBot converts written text into natural-sounding speech using AI-generated voices. It supports multiple languages and regional accents, making it useful for video voiceovers, presentations, educational materials, and audio content. Users can generate and download audio files, helping simplify narration workflows without requiring traditional recording equipment or voice talent.
 4.7
Audie AI
Text-to-Speech
Audie AI is an audiobook creation tool that converts written manuscripts into narrated audio using AI-generated voices. It helps authors and publishers simplify production, explore different narration styles, and reduce reliance on traditional recording studios. With voice selection, advertised voice cloning, and downloadable audio, it supports more accessible audiobook creation for independent creators.
 4.6
Speechelo
Text-to-Speech
Speechelo is a text-to-speech tool designed to help creators turn written scripts into voiceovers. It offers different voices, languages, tones, and audio adjustments for creating narration. Video creators, educators, marketers, and content teams can use it to produce audio for tutorials, presentations, promotional videos, and other digital content projects.
 4.7
Leelo AI
Text-to-Speech
Leelo AI helps you turn written content into natural-sounding speech without recording your own voice. You can choose from 800+ voices across 142 languages and accents, adjust available voice settings, generate audio, store files in the cloud, export recordings, and use generated speech commercially for different content and communication needs.