Google Cloud Speech-to-Text
Google Cloud Speech-to-Text helps developers turn spoken audio into text for applications, captions, voice commands, meetings, calls, and searchable content. With streaming recognition, multilingual support, model adaptation, speaker diarization, and multiple transcription methods, it provides speech recognition capabilities for applications and enterprise workflows. It fits teams seeking integrated transcription workflows.
What is Google Cloud Speech-to-Text?
Google Cloud Speech-to-Text is a cloud service that converts spoken audio into written text through APIs and speech recognition models. It supports short, long, and streaming audio, with features such as speaker diarization, model adaptation, automatic punctuation, noise robustness, and multilingual transcription. Developers can integrate transcription directly into applications and workflows. It suits teams needing scalable, integrated transcription workflows globally.
Google Cloud Speech-to-Text supports enterprise and developer use cases for converting speech into searchable text. It supports 85+ languages and variants, three recognition methods, streaming audio, speaker diarization, model adaptation, automatic punctuation, profanity filtering, and multichannel recognition. Chirp 3 was trained on millions of audio hours and 28 billion text sentences. The service also offers regional deployments, on-premises availability, and customer-managed encryption keys. New customers can receive up to $300 in Google Cloud credits. V2 pricing is $0.016 per minute.
- Developer / Parent Company: Google Cloud (Alphabet Inc.)
- Core Focus: Enterprise Speech Recognition (ASR), Chirp 3 Foundation Model, & Multilingual Transcription APIs
Use Cases:
- Transcribing high-volume call center audio, customer service calls, and IVR interactions with telephony-tuned models
- Powering real-time streaming captions, live subtitling, and interactive voice assistants across mobile and web applications
- Indexing massive video, podcast, and media archives to enable searchable text databases and automated metadata creation
- Deploying on-premises or regional speech pipelines for strict data sovereignty, GDPR, and enterprise compliance requirements
Technology:
- Chirp 3 universal speech foundation model architecture trained on diverse global acoustic and text datasets
- Streaming Recognize and Batch Recognize APIs supporting real-time gRPC bi-directional streaming and asynchronous Cloud Storage processing
- Speech adaptation and class phrase biasing (converting spoken numbers into formatted addresses, currencies, and dates)
Target Users:
- Enterprise cloud architects and software engineers integrating speech recognition into scalable GCP application stacks
- Contact Center as a Service (CCaaS) and UCaaS platforms automating agent assistance and customer analytics
- Media streaming networks and broadcast engineers requiring fast, automated video captioning and subtitling
- Content creators using writing tools to draft video scripts, educational courses, and technical documentation
Corporate Entity: Operates under Google LLC / Google Cloud (Mountain View, CA)
Key features of Google Cloud Speech-to-Text
Google Cloud Speech-to-Text's key features are
- Chirp 3 Foundation Model: Delivers high-accuracy speech-to-text recognition across 125+ languages and dialects with superior accent resilience.
- Real-Time Streaming & Batch APIs: Supports low-latency gRPC audio streaming as well as high-throughput asynchronous batch processing for files up to 8 hours long.
- Dynamic Batch Processing: Offers low-cost asynchronous transcription for non-urgent audio archives at a fraction of standard rates.
- Speaker Diarization & Multi-Channel Support: Automatically identifies individual speakers and separates audio channels for multi-person calls and meetings.
- Speech Adaptation & Phrase Biasing: Boosts recognition accuracy for domain-specific jargon, brand names, and rare industry terminology using custom phrase hints.
- Speech-to-Text On-Premises: Deployable inside private corporate data centers via containerized Kubernetes appliances for total data control.
- Data Residency & Security Compliance: Regionalized API endpoints, customer-managed encryption keys (CMEK), and compliance with HIPAA, SOC 2, and PCI-DSS standards.
Google Cloud Speech-to-Text Pricing
Google Cloud Speech-to-Text operates on a consumption-based per-minute billing model across V1 and V2 API versions, backed by volume discounts and committed savings plans.
V1 API Free Tier:
- 60 free audio minutes per month per Google Cloud billing account (applies to V1 API standard model recognition)
V2 API Pay-As-You-Go Rates:
- V2 Standard Recognition: $0.016 per minute (~$0.96 per audio hour) for the first 500,000 monthly minutes (scales down to $0.004/min above 2M minutes)
- V2 Dynamic Batch Recognition: $0.003 per minute (~$0.18 per audio hour) for asynchronous, lower-priority batch transcriptions
- V1 Medical / Telephony Models: $0.024 to $0.078 per minute for specialized domain models
- 1-year and 3-year Flexible Savings Plans offer an additional 10% to 20% discount on commit volume
Disclaimer: Minimum billing increments apply (e.g., 15-second minimum rounding per request). New Google Cloud accounts receive $300 in free cloud trial credits. For current regional rates, visit cloud.google.com/speech-to-text/pricing.
Who is using Google Cloud Speech-to-Text?
Google Cloud Speech-to-Text is designed for cloud architects, enterprise developers, and media platforms, including
- Global Contact Centers & CCaaS Platforms: Transcribing millions of customer calls and automating real-time agent support
- Media Networks & Video Platforms: Generating closed captions and subtitles across live streams and video libraries
- Healthcare & Clinical Systems: Processing medical consultations and phone triage using specialized HIPAA-compliant speech models
- Content Creators: Using writing tools to draft video scripts, educational courses, and technical documentation
Best Google Cloud Speech-to-Text Alternatives
Some of the strongest Google Cloud Speech-to-Text alternatives include
- Deepgram
- AssemblyAI
- Speechmatics
- AWS Transcribe
- Azure Speech Services
- Whisper
Pros and Cons of Google Cloud Speech-to-Text
Pros
- Powered by Google Chirp 3 foundation models delivering high accuracy across 125+ global languages
- Dynamic Batch pricing ($0.003/min) significantly lowers transcription costs for large audio archives
- Seamless integration with the broader Google Cloud ecosystem (Cloud Storage, BigQuery, Vertex AI)
- Offers speech-to-text on-premises containers for strict air-gapped infrastructure requirements
- Enterprise-grade compliance with CMEK encryption, HIPAA readiness, and regionalized data residency
Cons
- V2 API requires paying from the first minute without carrying over V1's 60-minute free allowance
- 15-second billing minimum rounding can increase costs for high-frequency short audio command requests
- Real-time streaming sessions enforce a 5-minute timeout limit, requiring custom reconnection logic
Why Choose Google Cloud Speech-to-Text?
Google Cloud Speech-to-Text is the premier choice for organizations building infrastructure on GCP or requiring broad global language coverage backed by Chirp foundation models.
- Leverages Google's Chirp 3 foundation speech models trained on millions of audio hours
- Reduces batch transcription costs to $0.18/hour via Dynamic Batch processing
- Integrates natively with GCP data warehousing and AI tools like BigQuery and Vertex AI
- Supports both cloud API execution and fully air-gapped on-premises container deployments
- Trusted by enterprise scaleups, CCaaS providers, and global media organizations worldwide
Google Cloud Speech-to-Text vs. Competitors
The main difference between Google Cloud Speech-to-Text, Deepgram, AssemblyAI, and AWS Transcribe is that Google Cloud Speech-to-Text is powered by Chirp 3 foundation models with native GCP integration and low-cost Dynamic Batch pricing ($0.18/hr), whereas Deepgram specializes in ultra-low latency real-time streaming, AssemblyAI focuses on developer-friendly audio intelligence APIs, and AWS Transcribe is tailored specifically for AWS infrastructure workloads.
| Feature / Tool | Google Cloud STT (cloud.google.com) | Deepgram | AssemblyAI | AWS Transcribe |
|---|---|---|---|---|
| Core Focus | GCP-Native Foundation Speech AI (Chirp 3) | Ultra-Fast Real-Time & Streaming ASR API | Developer Speech APIs & Audio Intelligence | AWS Ecosystem Managed Speech Recognition |
| Language Coverage | 125+ Languages & Locales | 30+ Languages | 99+ Languages | 100+ Languages |
| Dynamic Batch Option | Yes ($0.003/min or $0.18/hr) | Yes (Pay-as-you-go tiers) | Batch API Available | Standard Batch Tiers |
| On-Premises Option | Yes (Speech-to-Text On-Prem) | Yes (Self-Hosted Containers) | No (Cloud API Only) | No (AWS Cloud Only) |
| Starting Price Range | Free (V1 60 min) / $0.003–$0.016/min | Free Credits / ~$0.0036–$0.0045/min | Free Tier / ~$0.0025–$0.0062/min | Free Tier / ~$0.024/min |
| Best For | GCP native stack integration & enterprise batch pipelines | Ultra-low latency streaming for conversational voice bots | App developers building LLM audio intelligence workflows | AWS native cloud infrastructure deployments |
How do we rate Google Cloud Speech-to-Text?
| Parameter | Rating (out of 5) |
|---|---|
| Transcription Accuracy & Accent Resilience | 4.9 |
| Language Coverage (125+ Languages) | 4.9 |
| GCP Ecosystem Integration & Security | 5.0 |
| Batch Processing Cost Efficiency | 4.8 |
| Value for Money | 4.7 |
| Overall Score | 4.86 |
Google Cloud Speech-to-Text Review
Google Cloud Speech-to-Text stands out as an enterprise benchmark in the automatic speech recognition space. Powered by Chirp 3 speech foundation models, it offers exceptional transcription accuracy across complex regional accents and 125+ global languages. The introduction of Dynamic Batch processing ($0.18/hour) provides immense value for organizations transcribing historical audio archives at scale. While streaming sessions require custom reconnection handling due to 5-minute timeouts, its seamless integration with Google Cloud storage, BigQuery, and enterprise security frameworks makes it an essential ASR solution in 2026.
Conclusion
Google Cloud Speech-to-Text is a practical choice for developers and businesses that need scalable, API-based transcription. Its 85+ language and variant support, streaming recognition, speaker diarization, model adaptation, and enterprise controls make it suitable for diverse workflows. For your Techshark audience, its strongest appeal is combining flexible transcription features with Google Cloud infrastructure. There is no need to build speech models from scratch.
FAQ
What is Google Cloud Speech-to-Text used for?
Google Cloud Speech-to-Text converts spoken audio into text for applications, workflows, and content. You can use it for meeting transcripts, captions, voice commands, call analysis, and searchable audio. For your project, it is especially useful when you need scalable transcription through APIs, streaming recognition, multilingual support, and configurable speech models.
How many languages does Google Cloud Speech-to-Text support?
Yes. Google Cloud Speech-to-Text supports 85+ languages and variants, making it suitable for multilingual applications and international audiences. Chirp 3 extends multilingual recognition across more than 100 languages during training. Available language, model, feature, and regional combinations vary, so check Google’s supported-language documentation before selecting a production configuration today.
Does Google Cloud Speech-to-Text support real-time transcription?
Google Cloud Speech-to-Text supports three recognition methods: synchronous, asynchronous, and streaming. Streaming recognition returns results while audio is processed, making it useful for voice interfaces and live applications. Synchronous and asynchronous methods suit different post-processing needs, letting you choose an approach based on whether transcription must happen immediately or later.
How much does Google Cloud Speech-to-Text cost?
Google Cloud Speech-to-Text pricing depends on API version, channels, batch methods, and additional Google Cloud services. The current page lists Speech-to-Text V2 API pricing at $0.016 per minute. New Google Cloud customers can also receive up to $300 in free credits, subject to Google Cloud’s applicable terms and eligibility directly.
Can Google Cloud Speech-to-Text identify different speakers?
Yes. Speaker diarization can automatically predict which speaker produced each utterance, helping organize conversations with multiple participants. This is useful for interviews, meetings, customer calls, and discussions where identifying speakers matters. However, available diarization support depends on the selected language, model, region, and configuration, so verify compatibility carefully before implementation.
Can I customize Google Cloud Speech-to-Text for specific terminology?
Yes. Model adaptation lets you provide hints and boost specific words or phrases, improving recognition for domain-specific terminology and uncommon vocabulary. This can help when your application handles product names, technical language, addresses, or specialized expressions. For your Techshark research, it is a useful capability to highlight for workflows.
User Reviews
No reviews yet for Google Cloud Speech-to-Text.
Featured Tools
Featured AI tools from TechShark
Melody Genie
MelodyGenie is an AI-powered music generator that creates original songs from simple text prompts. Users can choose styles, moods, and genres, then instantly generate melodies and full tracks, making it easy for creators, marketers, and hobbyists to produce custom music without musical expertise.
Freemium
Kimi AI
Kimi AI is an advanced AI assistant developed by Moonshot AI that helps you chat, research, write, code, and automate tasks in one place. It supports web search, file analysis, and multimodal inputs, and can even run autonomous “agent” workflows to complete complex tasks end-to-end.
Freemium
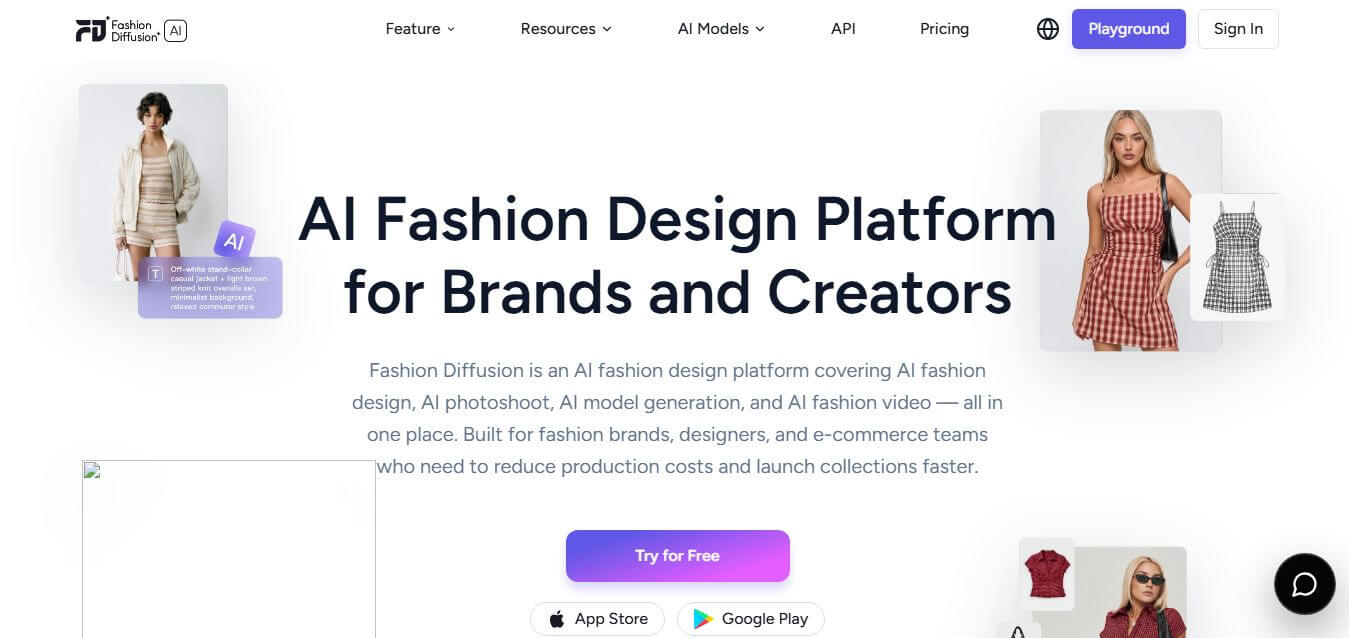
Fashion Diffusion AI
Fashion Diffusion is an AI-powered fashion design platform that helps brands and designers create clothing designs, virtual try-ons, AI models, product photos, and marketing visuals faster and cost-effectively.
Paid
Veo 4
Veo 4 AI is an AI video creation platform that generates dramatic videos from text, images, audio, and video prompts using realistic motion and synchronized sound.
Paid
Alternatives
Alternatives to Google Cloud Speech-to-Text
The best Google Cloud Speech-to-Text alternatives include Deepgram, AssemblyAI, Speechmatics, AWS Transcribe, Azure Speech Services, and OpenAI Whisper. These platforms provide automatic speech recognition (ASR), streaming transcription, and speech AI APIs. While Google Cloud Speech-to-Text excels with Chirp 3 foundation models, native GCP ecosystem integration, and low-cost Dynamic Batch processing ($0.18/hr), alternatives like Deepgram specialize in ultra-fast real-time streaming, and Speechmatics offers mid-sentence multilingual code-switching.
 4.9
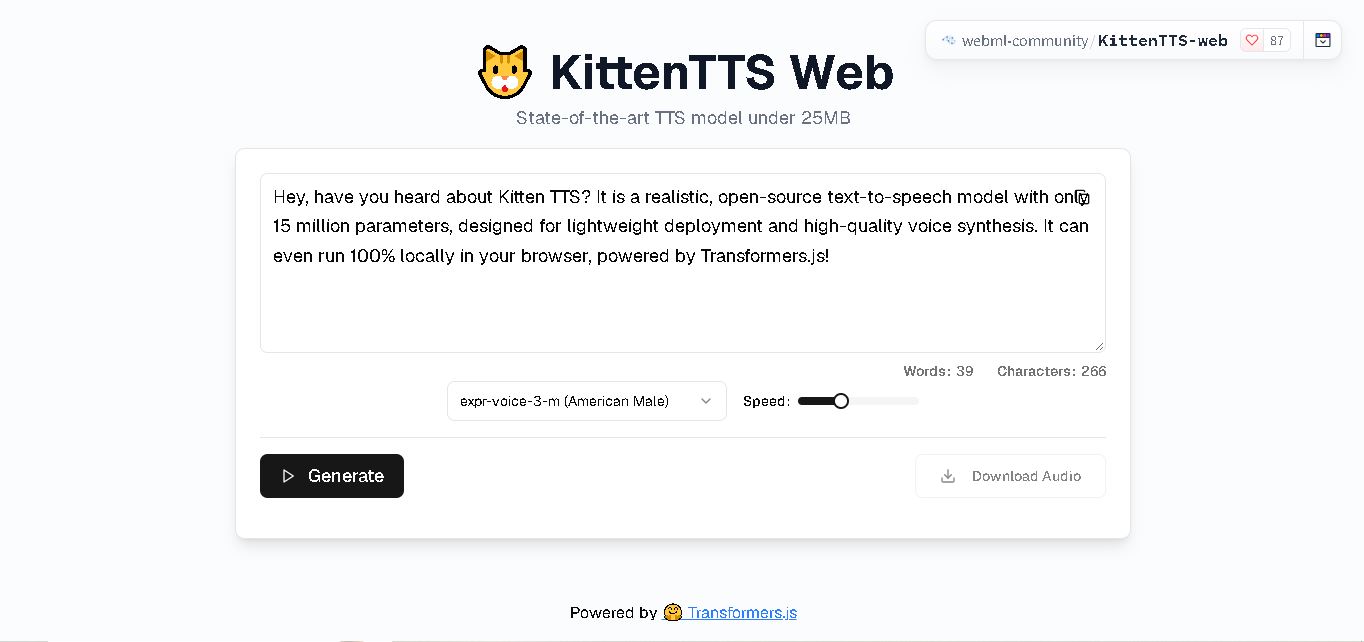
KittenTTS Web
Text-to-Speech
KittenTTS Web is a lightweight text-to-speech demo hosted on Hugging Face Spaces. It helps users explore how written text can be transformed into spoken audio using neural voice synthesis. The project is particularly relevant to developers, content creators, and accessibility-focused users interested in experimenting with compact speech generation technology directly through a web browser.
 4.9
Parler-TTS
Text-to-Speech
Parler-TTS is an open-source text-to-speech tool that transforms written content into natural-sounding audio. It lets developers describe voice characteristics using natural language, including pitch, speaking speed, and recording quality. With publicly available model weights, training resources, and customizable checkpoints, it supports experimentation, research, and tailored speech-generation applications across projects.
 4.9
IMS Toucan
Text-to-Speech
IMS Toucan is an open-source text-to-speech toolkit from the University of Stuttgart designed for multilingual speech generation. It converts text into audio and provides tools for inference, voice and prosody control, and model training. Supporting more than 7,000 languages, it serves developers and researchers exploring technology across linguistic contexts.
 4.8
Verbatik
Text-to-Speech
Verbatik AI helps users create realistic voiceovers, clone voices, generate music, and produce multimedia content using artificial intelligence. With multilingual speech, customizable voice settings, and developer APIs, it supports content creators, marketers, educators, and businesses. The platform simplifies audio production, video creation, and content localization from one workspace.
 4.8
Narration Box
Text-to-Speech
Narration Box is an AI voice generator for creating realistic voiceovers, audiobooks, podcasts, and educational audio from text. It offers over 1,500 AI narrators, 80+ languages and accents, voice cloning, and customizable emotional delivery. Its editing tools help creators produce consistent, multilingual audio content for personal and professional projects.
 4.7
AudioBot
Text-to-Speech
AudioBot converts written text into natural-sounding speech using AI-generated voices. It supports multiple languages and regional accents, making it useful for video voiceovers, presentations, educational materials, and audio content. Users can generate and download audio files, helping simplify narration workflows without requiring traditional recording equipment or voice talent.
 4.7
Audie AI
Text-to-Speech
Audie AI is an audiobook creation tool that converts written manuscripts into narrated audio using AI-generated voices. It helps authors and publishers simplify production, explore different narration styles, and reduce reliance on traditional recording studios. With voice selection, advertised voice cloning, and downloadable audio, it supports more accessible audiobook creation for independent creators.
 4.6
Speechelo
Text-to-Speech
Speechelo is a text-to-speech tool designed to help creators turn written scripts into voiceovers. It offers different voices, languages, tones, and audio adjustments for creating narration. Video creators, educators, marketers, and content teams can use it to produce audio for tutorials, presentations, promotional videos, and other digital content projects.
 4.7
Leelo AI
Text-to-Speech
Leelo AI helps you turn written content into natural-sounding speech without recording your own voice. You can choose from 800+ voices across 142 languages and accents, adjust available voice settings, generate audio, store files in the cloud, export recordings, and use generated speech commercially for different content and communication needs.